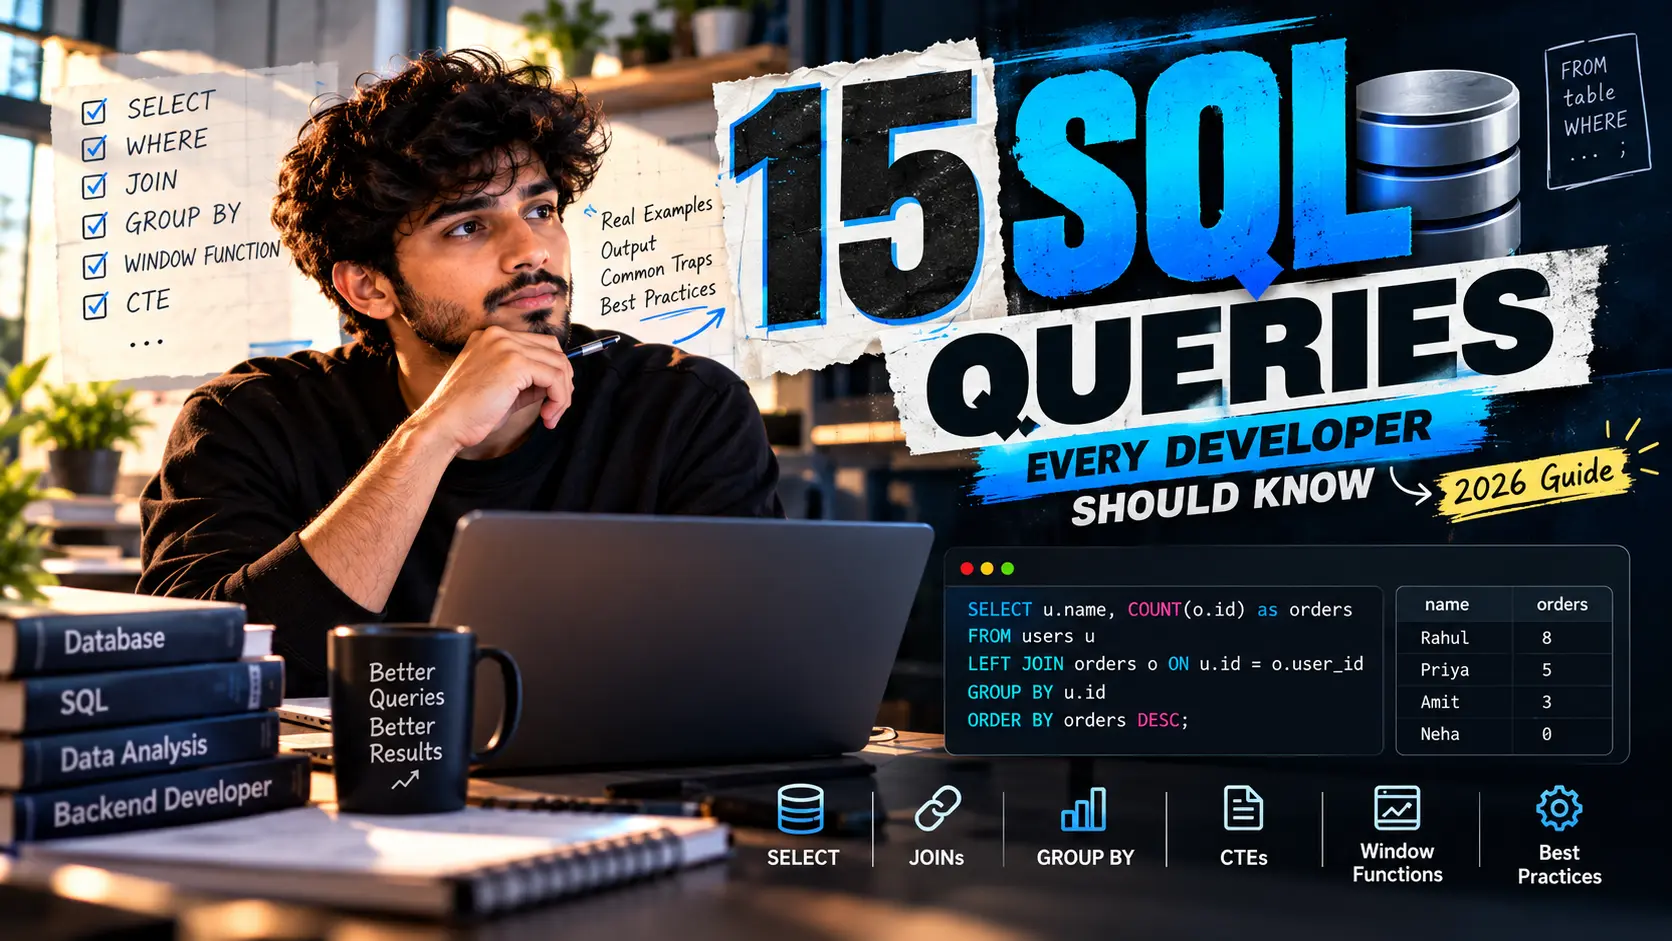
- 1Fifteen statements cover most day-to-day SQL: SELECT, WHERE, ORDER BY, GROUP BY, HAVING, two JOINs, aggregates, DISTINCT, CASE, subqueries, CTEs, window functions, ranking functions and INSERT, UPDATE and DELETE.
- 2WHERE filters rows before grouping and HAVING filters groups after aggregation. Mixing them up is the most common beginner error, and the database will reject WHERE COUNT(*) > 5 outright.
- 3A LEFT JOIN keeps unmatched rows from the left table, which makes it the standard way to find 'users with no orders'. An INNER JOIN silently drops them.
- 4Window functions calculate across related rows without collapsing them, and ROW_NUMBER, RANK and DENSE_RANK only differ when there are ties.
- 5UPDATE and DELETE without a WHERE clause change every row. Run the matching SELECT first, and use parameterized queries so user input can never rewrite your SQL.
15 SQL Queries Every Developer Should Know (2026 Guide)
Published: October 15, 2026 · Last updated: October 15, 2026 · 16 min read · By Veeresh Bashetti · Sources linked below
💡 Quick answer, if you're in a hurry: Learn these in four groups. Read and filter: SELECT, WHERE, ORDER BY, GROUP BY, HAVING. Join and reshape: INNER JOIN, LEFT JOIN, aggregate functions, DISTINCT, CASE WHEN. Go deeper: subqueries, CTEs, window functions, ROW_NUMBER and RANK. Change data: INSERT, UPDATE, DELETE. Then add five habits: use indexes, avoid SELECT *, use parameterized queries, check plans with EXPLAIN, and write readable SQL.
Table of Contents
- Why These 15 Queries Matter
- Set Up a Practice Database
- The 15 Queries at a Glance
- Phase 1 Read and Filter Data
- Phase 2 Join and Reshape Data
- Phase 3 Subqueries CTEs and Window Functions
- Phase 4 Change Data Safely
- The 5 SQL Best Practices in Detail
- What the Cheat Sheet Leaves Out
- Common Mistakes
- Free Videos to Go Deeper
- Copyable SQL Checklist
- Final Word My Honest Take
- Sources and Further Reading
- More Useful Resources
Why These 15 Queries Matter
SQL is one of the few skills that follows you across almost every developer role. In my guide to programming languages for different careers, SQL showed up in about 58.6% of Stack Overflow 2025 survey responses and sat at number 8 on the September 2026 TIOBE index. Whatever language you pick first, you will end up talking to a database.
This guide follows the structure of a popular infographic called "15 SQL Queries Every Developer Should Know". I could not find a creator credit on it, so I cannot name one. I like it because it lists the queries you actually reuse in real applications instead of every keyword SQL has. The explanations, the practice database, the output and the corrections below are my own, checked against the PostgreSQL and MySQL documentation and OWASP. Where I add nuance or disagree with the infographic, I say so.
One honest note about my own experience: I work with MySQL alongside Django and Node.js, so my habits lean toward MySQL. I have not used every database engine in production. To keep the examples portable, I wrote them in standard SQL and ran every one of them in SQLite 3.45.1, so the output you see below is real, not invented. Small syntax differences between engines are called out where they matter.
If you are building the frontend side first, my frontend developer roadmap for 2026 shows where databases fit. If you are deciding how your app talks to its data, read types of APIs and their use cases.
Set Up a Practice Database
Reading SQL teaches you little. Running it teaches you a lot. Every query in this guide uses the same three small tables, so you can paste the setup once and run everything yourself.
You can use any engine. The quickest zero-install option is SQLite (window functions need version 3.25 or newer). MySQL and PostgreSQL work too.
CREATE TABLE users (
  id      INTEGER PRIMARY KEY,
  name    TEXT NOT NULL,
  email   TEXT UNIQUE,
  country TEXT,
  age     INTEGER
);

CREATE TABLE employees (
  id         INTEGER PRIMARY KEY,
  name       TEXT NOT NULL,
  department TEXT NOT NULL,
  salary     INTEGER NOT NULL
);

CREATE TABLE orders (
  order_id INTEGER PRIMARY KEY,
  user_id  INTEGER,
  amount   INTEGER NOT NULL,
  FOREIGN KEY (user_id) REFERENCES users(id)
);

INSERT INTO users (id, name, email, country, age) VALUES
  (1, 'Asha',  'asha@example.com',  'India',   24),
  (2, 'Ravi',  'ravi@example.com',  'India',   17),
  (3, 'Meera', 'meera@example.com', 'Germany', 31),
  (4, 'John',  'john@example.com',  'USA',     45),
  (5, 'Priya', 'priya@example.com', 'India',   29);

INSERT INTO employees (id, name, department, salary) VALUES
  (1, 'Asha',  'Engineering', 90000),
  (2, 'Ravi',  'Engineering', 90000),
  (3, 'Meera', 'Engineering', 70000),
  (4, 'John',  'Sales', 60000),
  (5, 'Priya', 'Sales', 55000),
  (6, 'Kiran', 'Sales', 52000),
  (7, 'Dev',   'Sales', 51000),
  (8, 'Neha',  'Sales', 50000),
  (9, 'Om',    'Sales', 48000),
  (10, 'Sana', 'HR',    45000);

INSERT INTO orders (order_id, user_id, amount) VALUES
  (101, 1, 1500), (102, 1, 400), (103, 3, 2500),
  (104, 4, 1200), (105, 5, 300);
Notice two details on purpose. Ravi (age 17) has no orders, and Asha and Ravi have the same salary. Those two facts make the LEFT JOIN and RANK examples show something real.
ℹ️ Note: Salaries, names and amounts here are made-up sample data. Never practice UPDATE or DELETE on a production database.
The 15 Queries at a Glance
| # | Query | What it does | The trap to remember |
|---|---|---|---|
| 1 | SELECT | Retrieve columns from a table | Name columns instead of using * |
| 2 | WHERE | Filter rows | Runs before grouping, so no aggregates here |
| 3 | ORDER BY | Sort results | Without it, row order is not guaranteed |
| 4 | GROUP BY | Collapse rows into groups | Every selected column must be grouped or aggregated |
| 5 | HAVING | Filter groups | Use it for aggregate conditions only |
| 6 | INNER JOIN | Rows matching in both tables | Drops rows with no match |
| 7 | LEFT JOIN | All left rows plus matches | Non-matches show NULL |
| 8 | Aggregate functions | COUNT, SUM, AVG | COUNT(column) skips NULLs |
| 9 | DISTINCT | Remove duplicate rows | Applies to the whole selected row |
| 10 | CASE WHEN | Conditional logic in results | Always add an ELSE |
| 11 | Subquery | A query inside a query | NOT IN breaks when the list has NULL |
| 12 | CTE (WITH) | Named temporary result set | Great for readability |
| 13 | Window functions | Calculate across related rows | Rows are not collapsed |
| 14 | ROW_NUMBER / RANK | Number or rank rows | Only differ when values tie |
| 15 | INSERT / UPDATE / DELETE | Add, change, remove data | No WHERE means every row |
Phase 1 Read and Filter Data
Query 1: SELECT
Use it for: retrieving data from one or more columns.
SELECT name, email
FROM users;
This returns the name and email of all five users. SELECT says which columns you want, FROM says which table. Everything else in this guide builds on those two keywords.
Query 2: WHERE
Use it for: filtering rows by a condition.
SELECT *
FROM users
WHERE age > 18;
This returns Asha, Meera, John and Priya, and leaves out Ravi (17). WHERE supports comparisons (=, <>, >, <), AND, OR, IN, BETWEEN and LIKE.
One rule matters more than the rest: comparing with NULL needs IS NULL, not = NULL. A comparison against NULL is never true, so WHERE age = NULL returns nothing.
Query 3: ORDER BY
Use it for: sorting the result set.
SELECT *
FROM users
ORDER BY name ASC;
ASC is ascending and the default. Use DESC for descending, and sort by several columns with ORDER BY country, age DESC. If you skip ORDER BY, the database is free to return rows in any order, so never rely on the order you happened to see during testing.
Query 4: GROUP BY
Use it for: turning many rows into summary rows.
SELECT department, COUNT(*) AS total
FROM employees
GROUP BY department;
Result on the practice data:
| department | total |
|---|---|
| Engineering | 3 |
| HR | 1 |
| Sales | 6 |
The rule that trips people up: every column in SELECT must either appear in GROUP BY or be wrapped in an aggregate function. Select name here without grouping it and strict engines will refuse, while some lenient MySQL modes may return an arbitrary value instead of an error. Treat that leniency as a bug waiting to happen.
Query 5: HAVING
Use it for: filtering groups after they are formed.
SELECT department, COUNT(*) AS total
FROM employees
GROUP BY department
HAVING COUNT(*) > 5;
This returns one row: Sales with 6. The question people always ask is "why not WHERE?" Because WHERE runs before grouping, when COUNT(*) does not exist yet. I tested the wrong version, WHERE COUNT(*) > 5, and SQLite rejects it with "misuse of aggregate".
💡 Tip: A handy mental model is the logical order SQL evaluates a query: FROM, then WHERE, then GROUP BY, then HAVING, then SELECT, then ORDER BY. You write SELECT first, but it is evaluated late. That one fact explains most "why can't I use this here?" errors.
Phase 2 Join and Reshape Data
Query 6: INNER JOIN
Use it for: combining two tables, keeping only rows that match in both.
SELECT u.name, o.order_id
FROM users u
INNER JOIN orders o
  ON u.id = o.user_id;
Result: Asha (101), Asha (102), Meera (103), John (104), Priya (105). Ravi is missing because he has no orders. That is not a bug, it is what inner means. The u and o are table aliases, which keep joins readable.
Query 7: LEFT JOIN
Use it for: keeping every row from the left table, with matches from the right when they exist.
SELECT u.name, o.order_id
FROM users u
LEFT JOIN orders o
  ON u.id = o.user_id;
Now Ravi appears, with NULL in the order_id column. This leads to one of the most useful patterns in everyday SQL, finding rows with no related record:
SELECT u.name
FROM users u
LEFT JOIN orders o
  ON u.id = o.user_id
WHERE o.order_id IS NULL;
-- returns: Ravi
🛠 Proof of skill: You understand joins when you can explain, without running anything, why INNER JOIN returns five rows on the practice data and LEFT JOIN returns six.
Query 8: Aggregate Functions
Use it for: calculating one value from many rows.
SELECT COUNT(*)    AS total_employees,
       SUM(salary) AS total_salary,
       AVG(salary) AS avg_salary
FROM employees;
Result: 10 employees, 611000 in total salary, 61100.0 on average. The other two common aggregates are MIN and MAX.
Know the NULL behavior. COUNT(*) counts rows, while COUNT(column) counts only non-NULL values in that column, and AVG ignores NULLs too. On the practice data, after I set Ravi's age to NULL, COUNT(*) returned 5, COUNT(age) returned 4, and AVG(age) averaged only the four known ages.
Query 9: DISTINCT
Use it for: removing duplicate rows from the result.
SELECT DISTINCT country
FROM users;
Result: India, Germany, USA. DISTINCT applies to the entire selected row, so SELECT DISTINCT country, age returns unique pairs, not unique countries. If you find yourself adding DISTINCT to hide duplicates after a join, stop and check the join first. The duplicates usually mean the join is matching more rows than you intended.
Query 10: CASE WHEN
Use it for: adding if-then-else logic inside a query.
SELECT name,
       CASE
         WHEN age >= 18 THEN 'Adult'
         ELSE 'Minor'
       END AS age_group
FROM users;
Ravi comes back as Minor, everyone else as Adult. Always include ELSE. Without it, rows that match no condition return NULL, which is easy to miss. CASE also works inside ORDER BY and inside aggregates, for example SUM(CASE WHEN amount > 1000 THEN 1 ELSE 0 END) to count large orders.
Phase 3 Subqueries CTEs and Window Functions
Query 11: Subquery
Use it for: using the result of one query inside another.
SELECT name
FROM users
WHERE id IN (
  SELECT user_id
  FROM orders
  WHERE amount > 1000
);
Result: Asha, Meera, John. The inner query finds the users with an order over 1000, and the outer query fetches their names.
The classic trap is NOT IN. If the subquery's list contains even one NULL, NOT IN returns no rows at all. I tested this by adding an order with a NULL user_id: the query WHERE id NOT IN (SELECT user_id FROM orders) returned nothing, while the NOT EXISTS version still correctly returned Ravi.
SELECT name
FROM users u
WHERE NOT EXISTS (
  SELECT 1 FROM orders o WHERE o.user_id = u.id
);
⚠️ Heads up: Prefer NOT EXISTS (or the LEFT JOIN pattern from Query 7) over NOT IN whenever the column could contain NULL.
Query 12: CTE (WITH)
Use it for: naming an intermediate result so a complex query reads top to bottom.
WITH high_salary AS (
  SELECT *
  FROM employees
  WHERE salary > 50000
)
SELECT name, salary
FROM high_salary
ORDER BY salary DESC;
This returns seven employees, from Asha and Ravi at 90000 down to Dev at 51000. A CTE (common table expression) is like giving a subquery a name. You can chain several, each building on the last, which is far easier to read and debug than three levels of nested parentheses. Most major engines also support recursive CTEs for hierarchical data such as org charts, which is a good next topic once the basics feel easy.
Query 13: Window Functions
Use it for: calculating across a set of related rows without collapsing them.
SELECT name,
       department,
       salary,
       AVG(salary) OVER (PARTITION BY department) AS avg_salary
FROM employees;
The PostgreSQL documentation describes window functions as calculations across sets of rows related to the current row, and notes that an aggregate only acts as a window function when an OVER clause follows it. The key difference from GROUP BY is that every row survives. Each employee keeps their own row and also sees their department's average: 83333.33 for Engineering, 52666.67 for Sales, 45000 for HR.
Two rules to remember. PARTITION BY splits rows into groups for the calculation, and window functions run after WHERE, so you cannot use one inside WHERE. SQLite returned "misuse of window function" when I tried. If you need to filter on a window result, wrap the query in a subquery or CTE, as the next query shows.
Query 14: ROW_NUMBER and RANK
Use it for: numbering or ranking rows by an ordering.
SELECT name,
       salary,
       ROW_NUMBER() OVER (ORDER BY salary DESC) AS row_num,
       RANK()       OVER (ORDER BY salary DESC) AS rnk,
       DENSE_RANK() OVER (ORDER BY salary DESC) AS dense_rnk
FROM employees;
Result for the top four rows:
| name | salary | row_num | rnk | dense_rnk |
|---|---|---|---|---|
| Asha | 90000 | 1 | 1 | 1 |
| Ravi | 90000 | 2 | 1 | 1 |
| Meera | 70000 | 3 | 3 | 2 |
| John | 60000 | 4 | 4 | 3 |
Asha and Ravi tie on salary, and that is where the three functions disagree. ROW_NUMBER always gives unique numbers. RANK gives ties the same number and then skips, so Meera is 3rd. DENSE_RANK gives ties the same number without gaps, so Meera is 2nd. The PostgreSQL documentation describes rank() as rank with gaps and dense_rank() as rank without gaps. With no ties, all three return the same thing.
The pattern you will use most often is "top N per group", which combines this with a subquery:
SELECT *
FROM (
  SELECT name, department, salary,
         ROW_NUMBER() OVER (
           PARTITION BY department
           ORDER BY salary DESC
         ) AS rn
  FROM employees
) t
WHERE rn <= 2;
That returns the two highest-paid people in each department: Asha and Ravi in Engineering, Sana in HR, John and Priya in Sales.
Phase 4 Change Data Safely
Query 15: INSERT, UPDATE and DELETE
Use them for: adding new rows, changing existing rows and removing rows.
INSERT INTO users (name, email)
VALUES ('John', 'john@mail.com');

UPDATE users
SET email = 'new@mail.com'
WHERE id = 1;

DELETE FROM users
WHERE id = 1;
Name the columns in INSERT so your statement keeps working if someone adds a column later. The real danger is in the other two. An UPDATE or DELETE without a WHERE clause affects every row in the table.
A habit that prevents most disasters: write the SELECT first, check the rows it returns, then change the keyword.
-- 1. See exactly which rows you are about to change
SELECT * FROM users WHERE id = 1;

-- 2. Run the change inside a transaction
BEGIN;
UPDATE users SET email = 'new@mail.com' WHERE id = 1;
SELECT * FROM users WHERE id = 1;   -- verify
COMMIT;                              -- or ROLLBACK; if it looks wrong
⚠️ Heads up: The infographic shows the three statements together, which makes them look equally routine. They are not. Reading data is safe to repeat. Changing data is not, so treat UPDATE and DELETE with the most care of all 15.
The 5 SQL Best Practices in Detail
The infographic closes with five best practices. They are all sound. Here is what each one means in practice, including the nuance a one-line tip cannot carry.
1. Use indexes
Create indexes on columns you often use in WHERE, JOIN and ORDER BY. An index lets the database find rows without scanning the whole table. The trade-off is real, though: every index costs storage and slows down inserts, updates and deletes a little, because the index must be maintained too. Index the columns your slow queries actually use, not every column.
2. Avoid SELECT *
Select only the columns you need. It reduces the data sent over the network, and it keeps your code from breaking when someone adds, removes or reorders columns. It is perfectly fine while you explore a table in a console. Just do not ship it.
3. Use parameterized queries
This is the most important of the five. SQL injection happens when user input is mixed into SQL text. OWASP's guidance says developers should use prepared statements with variable binding, which force you to define all the SQL first and pass each parameter in separately, and that this stops an attacker from changing the intent of a query. OWASP's current Top 10 list files it under A05:2025-Injection.
The dangerous version builds the query with string concatenation:
// DON'T: user input becomes part of the SQL text
const rows = await db.query(
  "SELECT id, name FROM users WHERE email = '" + email + "'"
);
The safe version passes the value separately. Here it is with a placeholder, in the style used by MySQL drivers for Node.js:
// DO: the SQL is fixed, the value is passed as data
const [rows] = await db.execute(
  "SELECT id, name FROM users WHERE email = ?",
  [email]
);
And the same idea in Python's built-in sqlite3 module:
cur.execute("SELECT id, name FROM users WHERE email = ?", (email,))
Placeholder styles differ by driver (?, %s, $1, named parameters), so check your library's documentation. The principle is identical everywhere.
4. Use EXPLAIN
Put EXPLAIN in front of a query to see how the database plans to run it. The MySQL documentation says the output shows how tables are joined and in which order, and that it can help you see where to add indexes. When a query is slow, the plan tells you whether it is scanning the whole table or using an index. Syntax and output differ between MySQL and PostgreSQL, so read your own engine's documentation. One caution for PostgreSQL: EXPLAIN ANALYZE actually runs the statement, so wrap anything that changes data in a transaction you roll back.
5. Write readable SQL
Use meaningful names, consistent capitalization, one clause per line and clear aliases. A CTE usually beats three nested subqueries. You will read your own queries far more often than you write them, and a teammate will read them at the worst possible moment.
What the Cheat Sheet Leaves Out
Fifteen queries is a strong starting set, and no cheat sheet fits everything. These are the gaps I would fill next, in rough priority order.
| Topic | Why it matters |
|---|---|
NULL handling (IS NULL, COALESCE) | NULL breaks comparisons, NOT IN and averages in ways that look like wrong data |
| RIGHT JOIN and FULL OUTER JOIN | Completes the join family, though many developers rewrite RIGHT JOIN as a LEFT JOIN |
| UNION and UNION ALL | Combines results from separate queries, and UNION ALL is faster because it keeps duplicates |
| LIMIT, TOP and FETCH FIRST | Returns only the first N rows, but the keyword depends on the engine |
| CREATE TABLE, constraints and keys | Designing tables correctly prevents bad data before queries ever run |
Transactions (BEGIN, COMMIT, ROLLBACK) | Keeps multi-step changes all-or-nothing |
| String and date functions | Real data is messy, and each engine names these functions differently |
ℹ️ Note: SQL is standardized, but engines add their own dialects. Most queries in this guide run unchanged on MySQL, PostgreSQL and SQLite. Row limiting, date functions and some window features are where you will notice differences.
Common Mistakes
- Using WHERE for aggregate conditions. Use HAVING, and remember
WHEREruns first. - Using INNER JOIN when you need LEFT JOIN. Rows quietly disappear, and nothing warns you.
- Hiding join duplicates with DISTINCT. Fix the join instead.
- Trusting
NOT INwith nullable columns. UseNOT EXISTS. - Running UPDATE or DELETE without a WHERE. Write the SELECT first, then switch the keyword.
- Building SQL with string concatenation. Use parameterized queries every time user input is involved.
- Relying on row order without ORDER BY. The database does not promise any order.
- Memorizing syntax instead of practicing. Finish small projects. My story of why my first project failed quietly is a lesson in exactly that.
Free Videos to Go Deeper
You do not need to pay to learn SQL. Watch for the concepts, and always check the publication date, because tooling changes.
- SQL Tutorial - Full Database Course for Beginners (freeCodeCamp): about 4 hours, MySQL-based. The matching freeCodeCamp article lists every topic covered.
- PostgreSQL Tutorial: window functions: a written walkthrough of
ROW_NUMBER,RANKandDENSE_RANKwith tie examples, useful after Query 14. - MySQL: EXPLAIN statement: the official explanation of reading execution plans.
Prefer free tools while you learn? See my list of 9 truly free AI tools for developers.
Copyable SQL Checklist
Copy this into your notes or paste it into a study tracker.
Read
- I can write SELECT, WHERE and ORDER BY from memory
- I can explain why
WHERE COUNT(*) > 5fails andHAVINGworks - I can group data and filter the groups
Combine
- I can explain INNER JOIN vs LEFT JOIN using a real example
- I can find rows with no match using LEFT JOIN and IS NULL
- I know COUNT(*) and COUNT(column) can differ
Go deeper
- I wrote one query with a CTE and one with a window function
- I can explain ROW_NUMBER vs RANK vs DENSE_RANK on tied values
- I can write a "top 2 per group" query
Stay safe
- I always write the SELECT before an UPDATE or DELETE
- I use parameterized queries whenever user input is involved
- I have run EXPLAIN on at least one slow query
Final Word My Honest Take
If I had to compress this whole guide into one idea, it would be that SQL is a handful of building blocks that combine. You are not memorizing fifteen separate tricks. You are learning to filter, group, join and rank, then stacking those pieces. A top-N-per-group report is just a window function inside a subquery with a filter on top.
The fastest way to learn is to paste the practice schema from this guide into SQLite, MySQL or PostgreSQL and break things on purpose. Run the wrong WHERE COUNT(*) and read the error. Try the NOT IN trap with a NULL. Rank a tie. Mistakes you cause yourself stick far better than mistakes you read about.
Pick one query from this list today, run it, then change one thing and predict the result before you press enter.
Sources and Further Reading
Technical claims in this article were checked against the following sources in October 2026. Query output was produced by running every example in SQLite 3.45.1.
- PostgreSQL documentation: Window Functions: definition of window functions, the OVER clause requirement, and the difference between
rank()(with gaps) anddense_rank()(without gaps). This is an older documentation version, and the behavior described is long-standing. Check the current version for your release. - PostgreSQL Tutorial: Window Functions (Neon): worked examples of
ROW_NUMBER,RANKandDENSE_RANK - OWASP: SQL Injection Prevention Cheat Sheet: prepared statements with parameterized queries as the first defense
- OWASP: Query Parameterization Cheat Sheet: parameterized query examples, and SQL injection's category in the OWASP Top 10:2025 (A05:2025-Injection)
- MySQL Reference Manual: EXPLAIN: what EXPLAIN shows and how it helps with indexing decisions
- freeCodeCamp: SQL and Databases, A Full Course for Beginners: topics covered in the free video course
- Stack Overflow Developer Survey 2025: Technology: language usage survey, where SQL appears among the most used technologies
- TechRepublic: TIOBE Index September 2026: SQL's position on the TIOBE index (the figures are the ones I cited in my earlier languages guide)
SQL dialects differ between database engines, and documentation changes with each release, so confirm syntax against your own engine before running anything on real data. Examples are simplified for teaching.
This article is maintained and updated as tools change. If you spot outdated information, please use the Contact page to flag it.
About the Author
Veeresh Bashetti is a full-stack developer who builds Django and React applications and writes practical, project-tested guides for developers and students, with a focus on separating genuine industry trends from marketing hype. Read more on the About page.
More Useful Resources
- Best Programming Languages to Learn for Different Careers (2026 Guide)
- Types of APIs and Their Use Cases (2026 Guide)
- Frontend Developer Roadmap 2026: 12 Steps, in Order
- HTTP Status Codes Explained with Real Code Examples (2026)
- 5 Common Django Mistakes Beginners Make (and Fixes)
- More Tech Articles
Did you find this helpful?
FAQ